 🛠️ Dev Workshop Back to channel
The Model That Won't Chat: Inside Jev, the "System One" AI That Only Returns Answers and Choices
An AI model that refuses to chat sounds like a chatbot on strike. But that's genuinely the pitch for Jev, the first release from TypeSafe AI — and it might be the most interesting model launch of September 2026. Jev will never write you an essay, summarize a PDF, or apologize for misunderstanding your question. It does exactly one thing: you hand it some text or structured data, ask it typed questions, and it answers each one with a number — a probability, a choice, a score. No sentences. Ever. By design.
If that sounds useless, consider who built it: a ChatGPT co-creator who says our current models are "lightning in a bottle" that is "nonetheless not useful." And consider that within a week of launch, the company's API briefly buckled under developer demand, LangChain and Pydantic shipped first-class integrations, and Wikipedia already has an article. Here's everything a newcomer needs to know.
So what actually is Jev?
Jev is what TypeSafe calls a System One model — borrowing Daniel Kahneman's term for fast, intuitive thinking (Simon Willison prefers "decision models," which is honestly catchier). Where a large language model is optimized to produce text a human enjoys reading, Jev is optimized to produce typed, probabilistic decisions that software can use directly. The company's own one-liner: "Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out."
The shape of a call is simple. You send two things:
- a state — a string, an array of strings, or name-value pairs describing the thing to judge (a support ticket, an email, a log line, a game state), and
- one or more questions about that state.
Every question is evaluated in a single parallel pass — adding a dozen extra questions barely changes response time, and answers come back in roughly 70–500 milliseconds. Because the possible answers are defined by your schema in advance, the model is, in TypeSafe's words, unable to make a type error — the company calls the math behind that guarantee impossibility, not best-effort. The output is meant to be consumed by your code, not read by a human.
The three primitives: Noul, Choice, and Score
Jev asks you to pick from exactly three question types:
- Noul — yes/no questions. You state a proposition ("this message conveys urgency") and get back a probability between 0 and 1. Fun bit of trivia: TypeSafe's CEO confirmed on Hacker News that "Noul" is short for Bernoulli, as in the Bernoulli distribution. A support ticket saying "I've been trying to connect my Stripe account for 3 days, I'm losing sales, help ASAP" scores
noul: 0.999on urgency. Your code decides what 0.999 means — probably "put it at the top of the queue." - Choice — pick one option from a set you define. You get the selected option, a probability for every option, and a confidence score. The API supports up to 255 options.
- Score — rating against ordered levels you describe (say, "no follow-up needed" through "urgent"), returning a continuous score plus the underlying distribution.
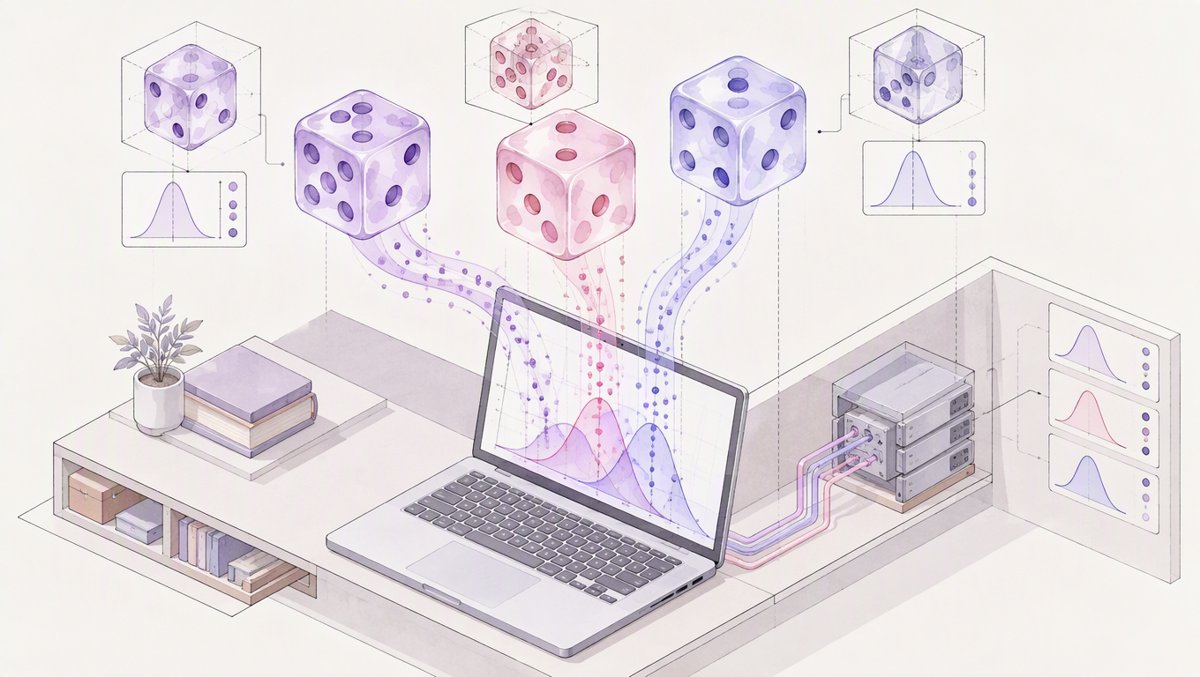
That's the entire interface. No chat history, no persona, no chain-of-thought to squint at. The Register's Joab Jackson summed it up memorably: "Basically, Jev is a classifier with brains."
The heartbreak origin story
The backstory is what makes this more than a novelty. Jev's creator, Diogo Almeida, spent about four years at OpenAI working on RLHF, InstructGPT, ChatGPT, and GPT-4 — the research that made chatbots chat. His verdict after leaving in 2024: "We have lightning in a bottle, and yet it is not useful." His diagnosis, as he told TechCrunch's Tim Fernholz: "The problem is we are optimizing for human language… We have been super good at human language for four years, but it's not useful for automation because computers speak a different language."
So in 2024 he co-founded TypeSafe AI in San Francisco with Erik Gafni and Sasha Sheng, spent roughly two years in stealth, and emerged on September 15, 2026 with Jev in limited early access and a $40 million seed round led by DCVC — reportedly at a $200 million valuation.
Oh, and the name? It's after William Stanley Jevons, the 19th-century economist of Jevons paradox fame — the observation that making a resource cheaper makes people consume more of it, not less. Almeida expects cheap machine intelligence to follow the same curve: decisions everywhere, in software that never talked to an AI before.
Under the hood (to the extent anyone can see)
TypeSafe hasn't published weights, a paper, or the architecture — outside observers suspect it's built on an open-weight LLM base. What the company does say: Jev is transformer-based, trained exclusively on synthetic data ("one of the best bets I've ever made in my life — better than RLHF," says Almeida), using a new training method called Reinforcement Learning for Calibrated Decisions (RLCD).
The key shift is what gets optimized. RLHF fine-tunes models toward what human raters prefer — which is how we got models that are, in Almeida's words, "super human at pleasing humans," confident even when wrong. RLCD instead optimizes calibration: higher stated confidence should genuinely mean higher accuracy, and similar inputs should get similar answers. Every answer ships with an honest uncertainty estimate, which is precisely the property you need before letting software act autonomously.
And because outputs are schema-constrained — the model selects from answer structures you defined ahead of time — TypeSafe claims Jev can't hallucinate in the LLM sense. It literally cannot emit a value outside your schema. What it can do is be wrong within the schema, which is what the probabilities are for.
The receipts — and their asterisks
The headline claims: 40–200× faster and 40–400× cheaper than frontier LLMs on decision-shaped tasks, with peak figures of 193.6× and 444.6× from TypeSafe's own "workflow evals." Pricing is $0.042 per million input tokens, output tokens free — cheaper than GPT-5 Nano's $0.05/M, with a per-decision cost of roughly a tenth of a cent.
To their credit, TypeSafe publishes the caveats next to the claims: the benchmark workflows were built by their own capabilities team (possible bias), the reference answers are the average of GPT-6 Astra and Fable 5.1 (biasing toward OpenAI and Anthropic), and the peak speedups are "on the higher end of real world gains." Pricing might be subsidized. Independent data points so far back the direction if not the peaks: a Vercel engineer reported replacing an OpenAI Luna-based safety classifier with Jev got results 5–18× faster with better accuracy; Bryo AI's CTO found Gemini slightly more accurate at classifying business emails but 10–20× more expensive, and praised Jev's confidence scores as "ideal for automating workflows."
The honest gaps: TypeSafe's own "jaggedness" documentation concedes Jev is currently weak with numbers, dates, and adversarial content, and skeptics like YouTuber Mo Bitar ask the fair question — "I know it's fast, I know it's cheap, but is it good?" The intelligence benchmarks are still thin.
Your first Jev call: the mental-model flip
Here's the part that trips up everyone who knows LLMs: the question does not go in the prompt. The prompt is only the material to judge. The questions live on your output type — one field, one question. Pydantic's docs call this "probably the most important concept" in the whole guide, and warn that a question pasted into the state will just get… judged as more text.
A support-ticket triage in Pydantic AI reads like this:
from typing import Literal
from pydantic import BaseModel, Field
from pydantic_ai import Agent

class Ticket(BaseModel):
    """Triage a support ticket."""
    urgent: bool = Field(description='Does this need a reply within the hour?')
    area: Literal['billing', 'bug', 'account', 'other'] = Field(description='Which team owns it?')

agent = Agent('typesafe:jev-latest', output_type=Ticket)
result = agent.run_sync(
    'You have charged me twice and my account is now overdrawn. I need this reversed today.'
)
print(result.output)  # urgent=True area='billing'
Two habits worth stealing from the docs:
- One judgment per field. Ask each field something a knowledgeable person could answer in a second. "Is this a good pitch?" fails silently — plausible number, low confidence. Split it into
large_market,technically_feasible,differentiated, and combine in code. - Extra questions are nearly free. Every field rides the same parallel request, so the lazy-adding-fields anti-instinct from token-priced LLMs is exactly wrong here.
LangChain exposes it as TypeSafeClassifier, and their new middleware is where this gets genuinely interesting: a ModelRouterMiddleware lets Jev decide whether a request deserves the cheap model or the powerful one, and an AutoModeMiddleware uses Jev as a cheap guardrail that checks risky tool calls (think bash) before they execute. Simon Willison shipped an llm-typesafe plugin the day after launch. The integration story, in other words, is already ahead of most models' week-one normals.
Week one: the ecosystem lost its mind
Because decisions cost a tenth of a cent and come back in ~150ms, developers immediately did what developers do: abused it gloriously.
There's jevchat, which turns Jev into a comically bad chat model by asking, at every step, "which symbol comes next?" — one Hacker News commenter called it "the digital equivalent of Morty speaking with the death crystal." There's jev-leftpad (padding strings via multiple-choice), jev-2048, bots speedrunning Doom (10 decisions/second, about $7/hour), Tetris, Catan, and chess — where Jev lost to the open-weight GLM 5.3 but ran far cheaper. Someone emulated a CPU on top of it and coined "JevOps," a meme about running all code on decision models. FPV Ventures' Nikunj Kothari built Jevable to collect the prototypes.
More practically: Browserbase powers browser-use agents "for fractions of a cent," there are live trading agents and email-triage pipelines, and search folks are using it for reranking — BM25 fetches 100 candidates, Jev scores their relevance. Open-weight recreations appeared within days (notably Kev, small decision models built on Qwen 3.5, plus a JevBench benchmark and open-source classifiers like Jeff and Nimble). One engineer, Archer Hume, probed it with 10,000 API calls and concluded Jev carries an LLM's world knowledge but computes decision probabilities directly from internal representations instead of predicting output text.
The fine print
Not everyone is cheering, and the concerns deserve more than a footnote.
The black box got blacker. Willison's sharpest observation: with an LLM you can at least ask for a rationale, even if it might be confabulated. Jev gives you a floating-point number, full stop. "If Jev marks something as spam, which content signals tipped it off?" His own experiment — asking Jev to rate Bay Area cities — produced rankings he could only describe as "Huh." Bias baked into the weights is now delivered without even the fig leaf of an explanation, which is why he argues evals and structured experiments matter more for Jev projects than for LLM ones (though they're delightfully cheap to run).
Hallucination didn't die — it moved. Armin Ronacher (of Flask and Ruff fame, now CTO at Earendil) put it well: Jev "delegates the hallucination problem a little bit to the user." If the model says 50%, maybe it's a coin toss and you disregard it; at 95% you act. The judgment shifts from the model's output to your thresholds — which is more honest, but still judgment.
It's not an LLM replacement. It can't write, can't reason through open-ended problems, and TypeSafe says so plainly. Every serious writeup lands on the same framing: use an LLM for open-ended reasoning and generation, Jev for the hundreds of small structured decisions around it — routing, triage, scoring, guarding.
Should you care?
Anthropic researcher Andrej Karpathy thinks Jev "revealed latent demand that was under-invested into because of a race to higher intelligence" — demand, as he put it, for "a single-token LLM with low latency and acceptable intelligence." That's the real story. For four years the industry optimized models to talk to humans; Jev is the first serious commercial bet that the bigger market is models talking to software.
Almeida's own vision is endearingly un-grand: "smart software all over the place in a way that's emergent and distributed, much more like the early internet than the mega apps people are trying to build right now." Asked if TypeSafe is a frontier lab, he said the main product of frontier labs "is fear or hype. I would like our main product to be intelligence."
If you build anything that branches on a judgment — support queues, moderation, routing, guardrails, any if statement that really needed a tiny bit of common sense — Jev is worth an afternoon. Ten thousand test calls cost about a dollar. Just put the question on the field, not in the prompt.
Sources
- Introducing System One Models & Jev — TypeSafe AI Blog (Diogo Almeida, Sep 15, 2026)
- A new kind of AI model from a ChatGPT inventor is thrilling developers — TechCrunch, Tim Fernholz (Sep 18, 2026)
- Jev introduces a new shape of LLM—System One, aka Decision Models — Simon Willison (Sep 21, 2026)
- Shut up and calculate: Jev's new AI primitives for coders — The Register, Joab Jackson (Sep 23, 2026)
- What Is Jev? A Guide to TypeSafe AI's System One Model — LangChain (Sep 17, 2026)
- TypeSafe (Jev) — Pydantic AI Docs
- Jev (AI model) — Wikipedia